Direct Answer: Data analysts eliminate brittle CSV exports and database ETL bottlenecks by leveraging aiFetchly's embedded SQLite ingestion engine. By combining automated column schema inference, transactional WAL-mode streaming, and native on-device SQL execution directly on NVMe disk, aiFetchly converts high-throughput web scraping batches into indexed relational databases without requiring external cloud databases or Python glue code.
The Bottlenecks of Traditional Web Data Pipelines
In modern quantitative data analysis, transforming unstructured web content into structured relational datasets remains a notorious friction point. Analysts scraping thousands of product specifications, pricing matrices, or economic directories routinely encounter three structural obstacles:
- Flat-File Degradation: Exporting web scrapers to flat CSV or JSON files creates unindexed data lakes. Querying multi-gigabyte flat files requires heavy memory overhead, easily crashing local Pandas dataframes.
- Cloud Warehouse Overhead: Streaming exploratory web data into cloud data warehouses (such as Snowflake, BigQuery, or hosted PostgreSQL) introduces recurring egress costs, cloud ingestion lag, and complex credentials management.
- Schema Fragility: Dynamic web pages frequently alter column counts, introduce nested null values, and change date formats, causing rigid database ingestion scripts to fail midway through overnight scraping jobs.
The aiFetchly desktop platform eliminates these bottlenecks by integrating an enterprise-grade SQLite ingestion engine directly into its desktop scraper.
Automated Schema Inference & Normalization
Rather than forcing analysts to manually define DDL schemas before initiating a crawl, aiFetchly inspects incoming DOM tables and JSON payloads dynamically:
- Automatic Type Casting: The engine evaluates incoming cell contents across rows, accurately inferring column data types—differentiating between signed integers, floating-point decimals, ISO-8601 timestamps, and text strings.
- Deterministic Column Sanitization: Column headers with irregular spacing, special characters, or duplicate names are automatically normalized into clean SQL identifiers.
- Composite Uniqueness & Deduplication: Analysts can flag composite primary keys (such as
sku_idandtimestamp) directly within the ingestion settings, automatically handling duplicate records withON CONFLICT DO UPDATEupsert logic.
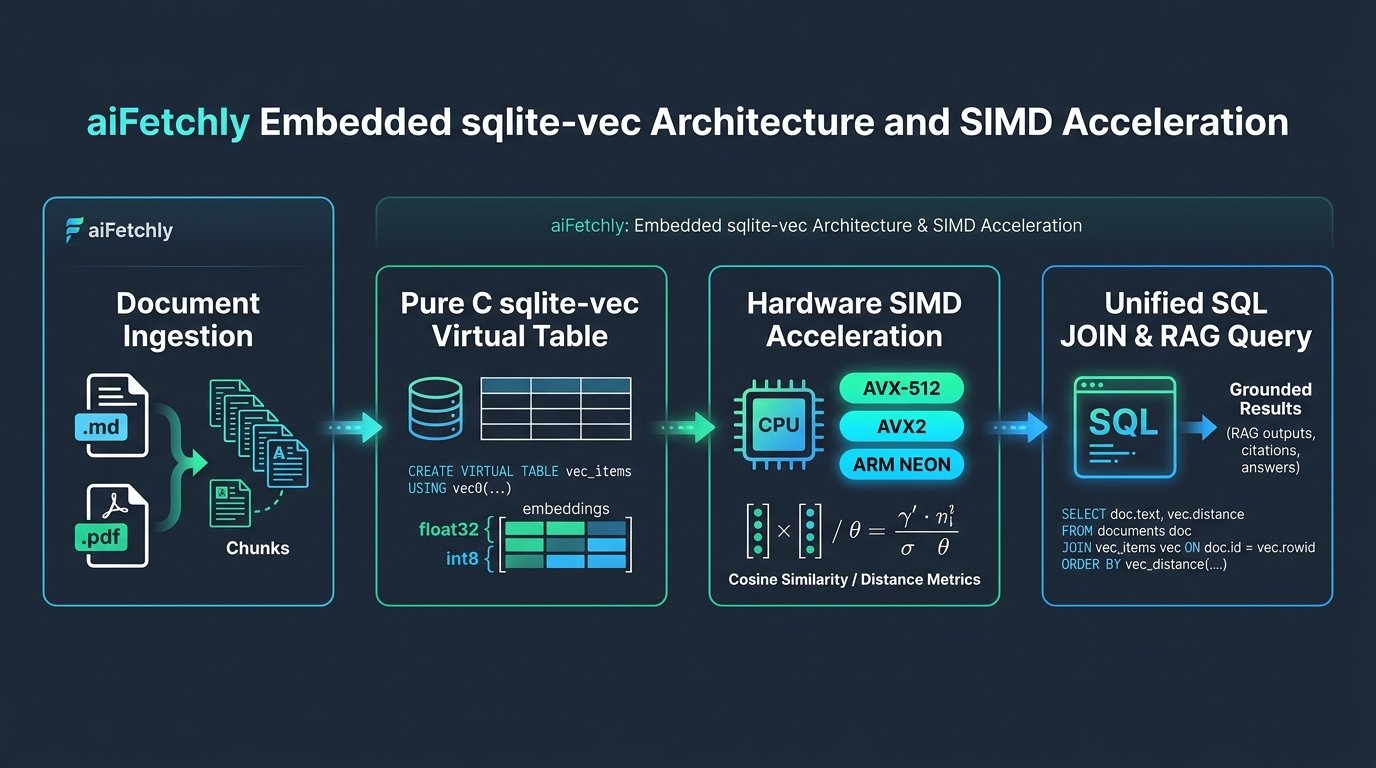
High-Throughput Streaming with WAL Mode
To support simultaneous high-speed scraping and analytical querying, aiFetchly configures embedded SQLite instances in Write-Ahead Logging (WAL) mode:
- Concurrent Ingestion & Interrogation: Headless Chrome DevTools Protocol (CDP) threads stream extracted records directly to NVMe storage without locking the database, allowing analysts to run complex SQL aggregations or AI queries simultaneously.
- Direct Desktop Interoperability: Because SQLite stores entire databases in a single portable
.dbfile, analysts can immediately connect local BI tools (like DBeaver or Tableau) or query tables using AI Chat V2. Schema configurations and performance tuning options are available in the aiFetchly documentation.
Zero-Egress Relational Power
Stop managing fragile CSV files and costly cloud warehouses for exploratory web data. By uniting automated schema inference with native desktop SQLite storage, aiFetchly provides data analysts with an agile, high-throughput database engine directly on their machine.
aiFetchly is a local-first desktop AI business agent (free to download). Home: aifetchly.com · aifetchly.com: www.aifetchly.com
About the author
- aiFetchly - local-first desktop AI agent for marketing outreach. https://www.aifetchly.com
Comments
Join the discussionNo comments yet. Be the first to comment.