Direct Answer: Data analysts can ingest public web content into aiFetchly RAG by navigating to the Knowledge Library, selecting Website Import (Single Page, URL List, or Site Crawl), configuring same-origin depth and duplicate policies, and initiating automated extraction. The desktop engine strips HTML boilerplate, converts text into clean Markdown, and generates vector embeddings locally.
In 2026, building grounded Retrieval-Augmented Generation (RAG) pipelines for market research often fails at the data ingestion phase. Web pages are cluttered with navigation menus, footer disclosures, cookie banners, and dynamic JavaScript bundles. Manually saving HTML files or copying text fragments introduces noise into vector indexes, leading to degraded semantic search results.
The aiFetchly desktop application solves this challenge with its native Website Import engine. Rather than relying on cloud middleware or third-party web scrapers, aiFetchly crawls target URLs directly from your workstation, extracts main readability text into sanitized Markdown, and indexes chunks into your local Knowledge Library. Here is a step-by-step guide for data analysts to turn public web sources into searchable RAG knowledge.
Step 1: Open Knowledge Library and Choose Import Mode
- In aiFetchly, navigate to Knowledge in the left navigation sidebar.
- Click Import Website in the top header.
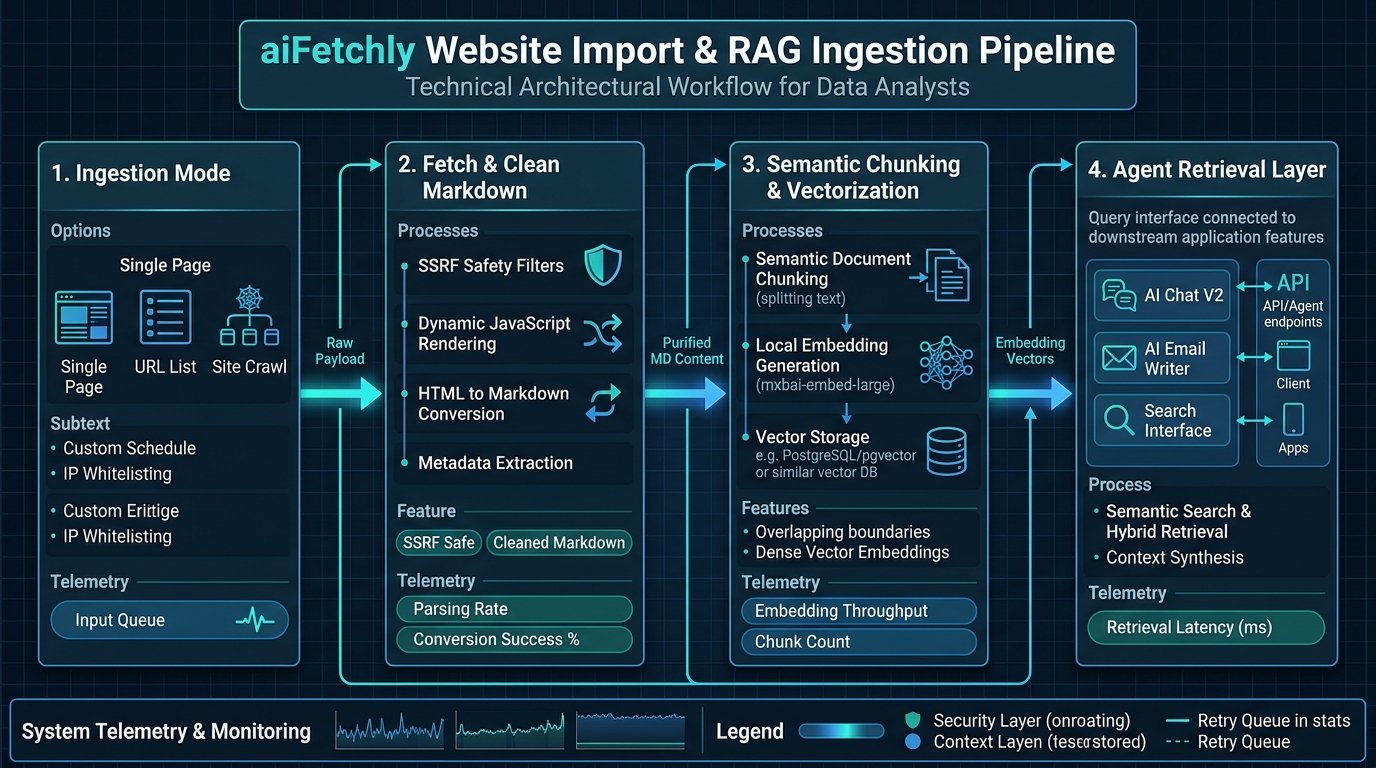
- Select your ingestion mode from the Website Import dialog:
- Single Page: Enter one target URL (e.g., a specific competitor pricing page) with an optional custom title override.
- URL List: Paste up to 50 curated URLs (one per line) for batch evaluation.
- Site Crawl: Enter a root URL (e.g., an industry documentation hub or public knowledge base) to recursively crawl same-origin links.
Step 2: Configure Crawl Boundaries and Duplicate Policies
For Site Crawl or URL List modes, configure the operational thresholds:
- Max Pages: Define an ingestion ceiling between 1 and 100 pages (default: 20) to keep embedding workloads bounded.
- Max Depth: Set how many link-hops to follow from the root URL (0–4, default: 2). The crawler automatically adheres to a strict same-origin boundary.
- Duplicate Policy: Choose
Skip duplicates(default) to ignore previously ingested URLs, orAllow duplicatesto store point-in-time competitive snapshots. - Common Metadata: Add categorization tags (e.g.,
competitor-intel,q4-pricing) and an author descriptor.
Step 3: Run Extraction and Inspect Markdown Conversion
Click Import. The real-time progress monitor tracks crawling activity:
- aiFetchly’s browser-based scraper renders dynamic content and isolates primary semantic containers (
article,main, document wrappers). - It strips scripts, style blocks, and navigation chrome, converting body text into structured Markdown.
- Built-in security filters automatically reject private IP ranges, loopback addresses (
localhost), and cloud metadata endpoints (169.254.169.254) to ensure SSRF protection.
Step 4: Verify Vector Indexing and Query via AI Chat
Once completed, each webpage appears in your Knowledge Library as a distinct document named {hostname}-{path}-{hash}.md:
- Documents are automatically split into overlapping semantic chunks and vectorized into local embeddings.
- Open AI Chat V2 or the AI Email Writer and query your ingested data immediately: "Summarize competitor tier changes based on our imported pricing docs."
By streamlining public web crawling into an automated Markdown RAG pipeline, aiFetchly enables data analysts to build high-fidelity intelligence repositories in minutes.
aiFetchly is a local-first desktop AI business agent (free to download). Home: aifetchly.com · docs intro: docs.aifetchly.com/docs/getting-started/introduction
About the author
- aiFetchly - local-first desktop AI agent for marketing outreach. https://www.aifetchly.com
Comments
Join the discussionNo comments yet. Be the first to comment.